news

Beyond token-maxing: How US Bank AI chief navigates costs

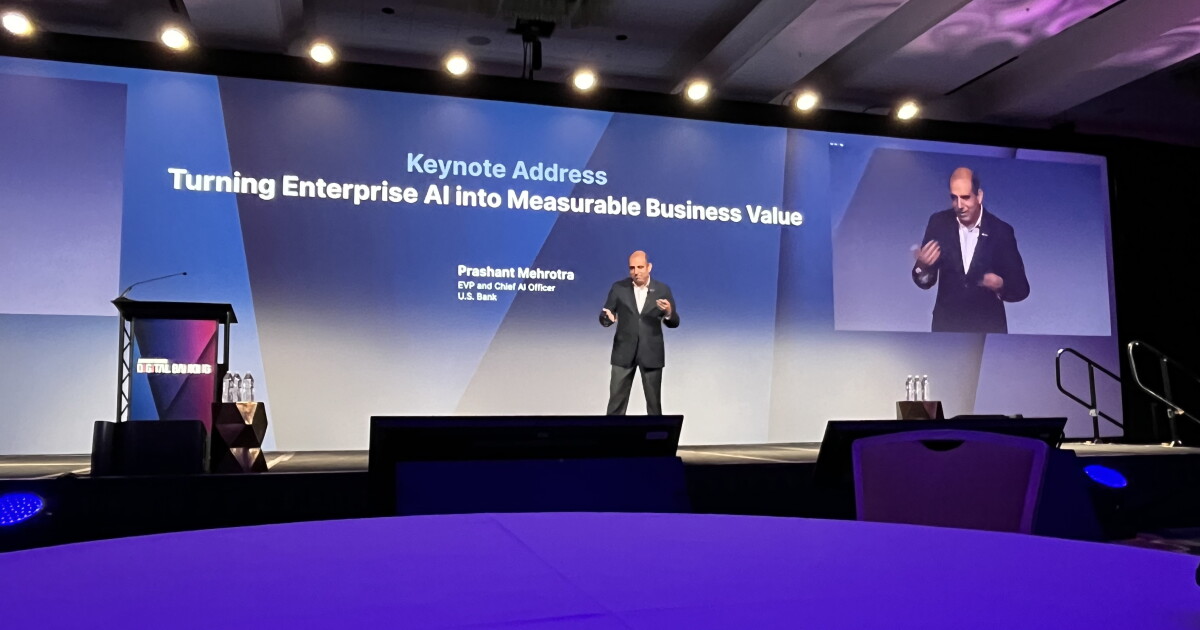
U.S. Bank chief AI officer Prashant Mehrotra tells American Banker the bank never ran token maxing. Every proposed use case is bucketed by whether it drives growth, cuts cost, or merely feels productive — and the last bucket loses.

Published 2026-07-30Source: American Banker
American Banker source artwork

Why it matters

Mehrotra credits three forces for the retreat: model providers raising prices, an experimentation phase that has ended, and teams finally seeing enough value to operationalise it. A cost-discipline account from a regulated buyer, not a vendor.

Tokenmaxxing read

His filter is frequency, not sophistication: a dazzling use case that fires once a month loses to dull high-volume work with a measurable baseline. Experiments are timeboxed and killed when they miss, so the spending decision lands before any tokens burn.

Source takeaway

A Q&A, so every claim is the bank’s own framing with no independent verification and no spend figures. Useful for the operating model — evangelise, educate, enable, execute, and reuse over reinvention — not for benchmarking what U.S. Bank pays.
Topic links

Related projects

Tools that match this angle

#1Direct
Routing

LiteLLM

BerriAI/litellm

An OpenAI-compatible gateway and SDK for calling many model providers with budgets, logging, load balancing, guardrails, and cost tracking.

59.3K11.6KSource-available
gatewaycost-trackingrouting
#2Direct
Observability

Langfuse

langfuse/langfuse

Open-source LLM engineering platform for observability, traces, metrics, evals, prompt management, datasets, and playground workflows.

34.9K3.8KSource-available
tracesevalscosts
#10Direct
Routing

Portkey Gateway

Portkey-AI/gateway

An AI gateway for routing across LLMs with guardrails, provider abstraction, and an OpenAI-compatible API surface.

13.1K1.3KMIT
gatewayguardrailsrouting
Related feed

More source-linked context

Generated Tokenmaxxing editorial thumbnail for Enterprise AI budgets break at the handoff to production
long-formEC
long-form

Enterprise AI budgets break at the handoff to production

Express Computer interviews New Relic India's Ganesh Narasimhadevara on why AI bills keep climbing while the blended cost per million tokens has fallen over a year, from $18.40 in Q1 2025 down to $6.07 in Q1 2026.

tokenmaxxingai-spendcost-governance
Read note
Cisco Newsroom source artwork
newsCN
news

Cisco's Splunk adds Tokenomics to track coding-agent token spend

At Splunk .conf on Sept. 15, Cisco added a Tokenomics module to Splunk Agent Observability. It attributes token spend across AI agents and across employees' use of coding agents, naming Claude Code, Codex and Cursor.

ai-spendcoding-agentsllm-observability
Read note
PYMNTS.com source artwork
newsP
news

AI Agents Just Got Their Own Company Credit Cards

Mercury launched Agent Cards through Mercury Spend: virtual cards an AI agent spends from inside company-set rules, with transactions outside them declined automatically and no way for the agent to raise its own limit.

tokenmaxxingagentsai-spend
Read note